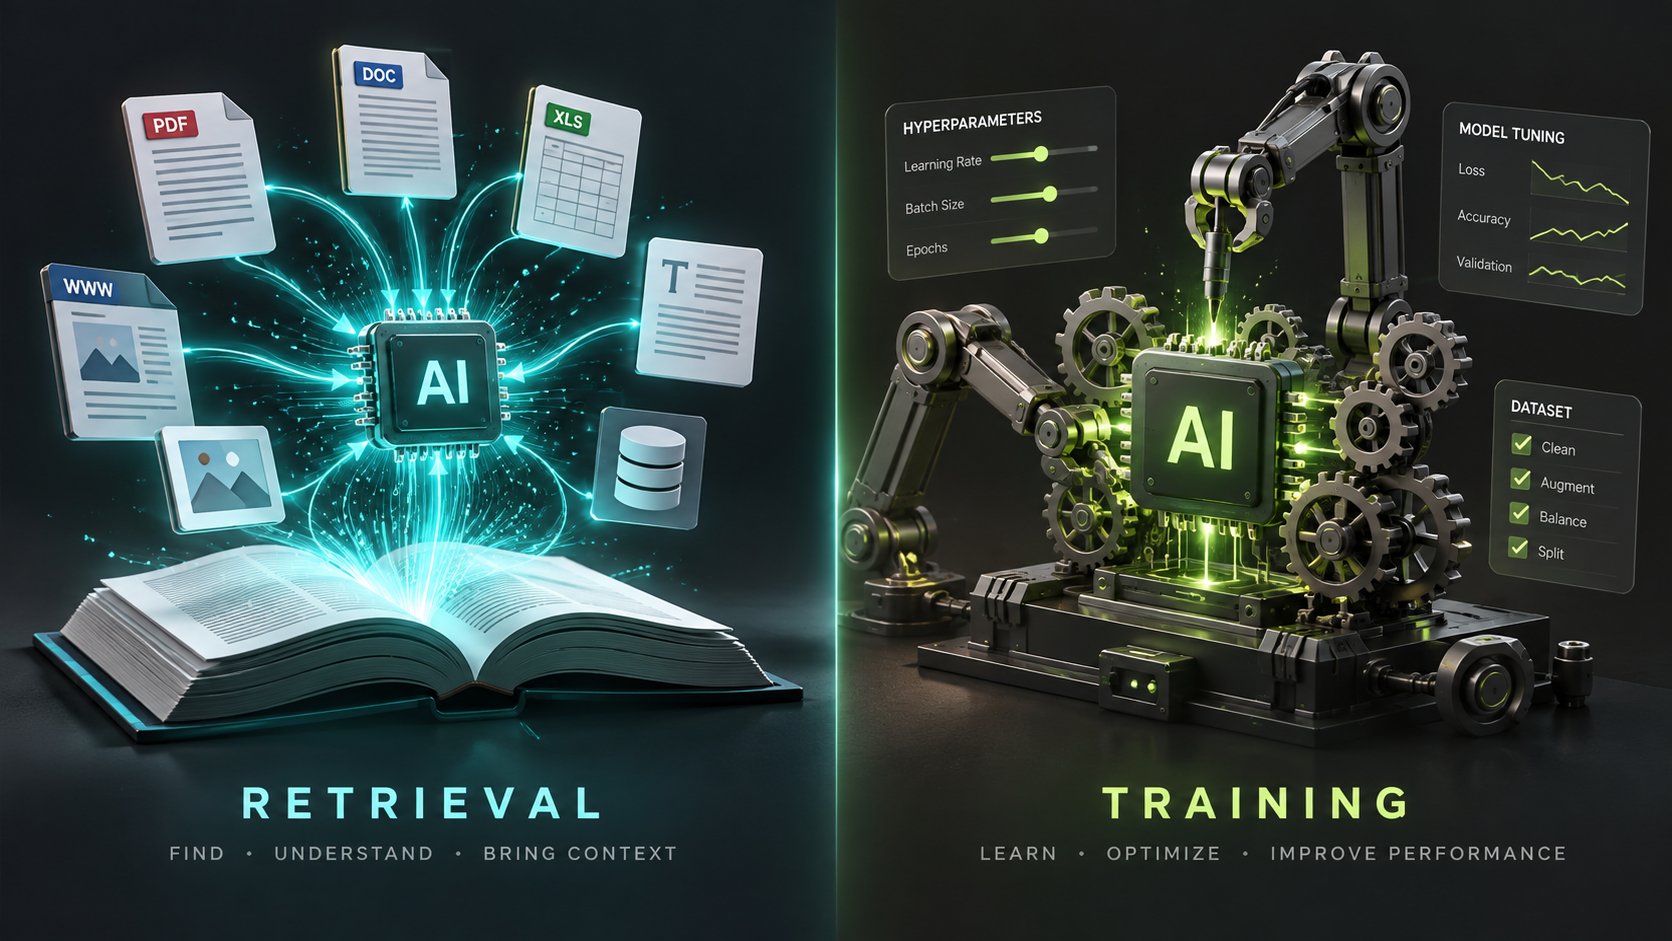
When a business wants a language model to work with its own information, two options come up quickly: RAG (retrieval-augmented generation) and fine-tuning. They are often treated as competing choices, and teams often pick the wrong one.
Most teams choose fine-tuning when they actually need retrieval, and retrieval when what they actually need is better data. This guide explains both in plain terms and helps you decide.
1. What a language model knows, and what it does not
A large language model learns from a huge amount of public text, up to a certain date. It does not know:
- Your internal documents, policies or products
- Anything that happened after its training
- Your customers’ data
So the question is how to give the model your knowledge. RAG and fine-tuning are two very different ways of doing that.
2. What RAG is
RAG means: before the model answers, look up relevant information from your own documents and give it to the model along with the question. It is like an open-book exam. The model does not memorise your documents; it reads the relevant pages each time.
A typical RAG system:
- Splits your documents into pieces and indexes them for search.
- When a question comes in, finds the most relevant pieces.
- Sends those pieces with the question to the model.
- The model answers using that information, and can cite where it came from.
3. What fine-tuning is
Fine-tuning means training an existing model further on your own examples, so its behaviour changes permanently. It is like training an employee: you do not hand them a manual every time, you teach them a specific job until it becomes habit.
Fine-tuning is good at teaching a model how to respond: a format, a tone, a specific task. It is much weaker at teaching it facts, especially facts that change.
4. The most common mistake
The most common mistake is fine-tuning a model to teach it your company’s information. It sounds logical, but it usually goes badly:
- The model may still get facts wrong, and confidently.
- When your information changes, you have to train it again.
- You cannot easily see where an answer came from.
If your problem is “the model does not know our information”, you usually need RAG, not fine-tuning.
5. When to choose RAG
- Your information changes: update the documents and the answers update too.
- You need sources: users or auditors want to see where an answer came from.
- Access matters: different users should only get answers from documents they are allowed to see.
- You want to start quickly: RAG can be built and improved without training a model.
Typical examples: internal knowledge assistants, customer support over product documentation, and question-answering over policies and contracts.
6. When to choose fine-tuning
- You need consistent format or style: always producing output in a strict structure, or in your brand’s voice.
- The task is narrow and repeated: such as classifying support tickets or extracting specific fields.
- You want a smaller, cheaper, faster model: a small fine-tuned model can sometimes match a large general model on one specific task, at lower cost and latency.
- Prompting alone is not reliable enough, even after careful prompt design.
7. When to use both
They are not opposites. Many production systems use RAG for knowledge and fine-tuning for behaviour: the model retrieves the right information and has been trained to answer in exactly the right format. Start with one, measure, and add the other only if you need it.
8. What each one costs
- RAG: building the retrieval system, storing and indexing documents, and slightly longer prompts on every request. Usually cheaper to start and easy to update.
- Fine-tuning: preparing high-quality training examples, running the training, and retraining whenever requirements change. Preparing the data is often the biggest cost, and the most underestimated.
9. Before choosing either: build an evaluation set
Whatever you choose, first build a set of real questions with known good answers. Without it, you cannot tell whether RAG, fine-tuning, a better prompt or better data actually improved anything.
Often, the evaluation set shows the real problem is neither option: it is missing, outdated or badly organised source data. That is when “better data” is the answer.
10. Quick decision checklist
| If your main problem is… | Start with |
|---|---|
| The model does not know our information | RAG |
| Our information changes often | RAG |
| We need to show sources | RAG |
| Output format or tone is inconsistent | Fine-tuning |
| One narrow task at high volume, and cost matters | Fine-tuning |
| Answers are wrong even with the right documents | Fix the data and evaluation first |
Not sure which approach fits your use case? We can help you decide before you build.